Section 5: Seven Records and One Very Large Array - Data Modeling
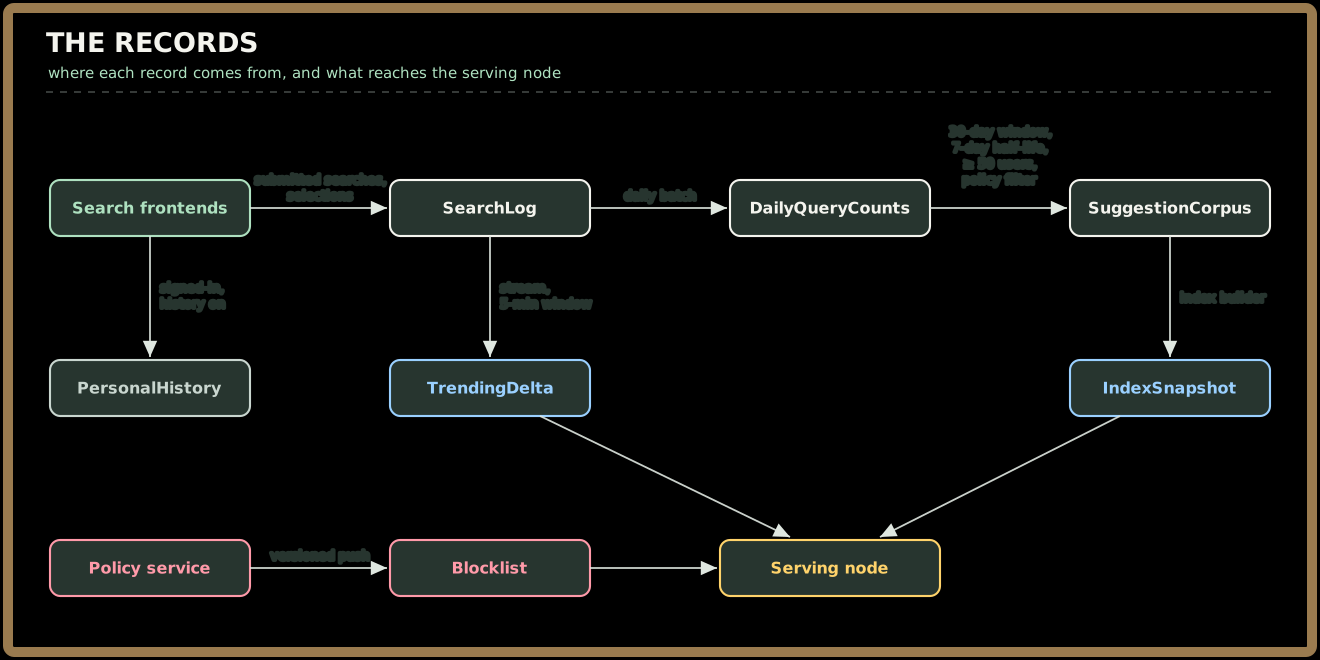
Executive Summary: A typeahead's data splits into two worlds. The learning side holds large, append-only records: the search log, daily per-query counts with HyperLogLog sketches of distinct users, and the filtered suggestion corpus. The serving side holds small, read-only artifacts: an immutable index snapshot, a per-minute trending delta and a versioned blocklist. Per-user history lives apart, in its own store. We follow their lineage, then lay out the ~20 GB snapshot: a node array, edge labels as offsets into a string table, and 15 query ids per node, worked through Maya's chicago mara.
The interviewer looks at the API from Section 4: "So what's actually behind /v1/suggest? What do you store?"
You: "Two kinds of data, kept apart. What we learn from is big, append-only and processed offline. What we serve from is small, immutable and held in RAM. Nothing the suggest service reads is a row someone updates."
The Records
| Record | Key | Fields | Size | Owner and lifetime |
|---|---|---|---|---|
| SearchLog | event id, timestamp | query text, timestamp, locale, hashed user id, region, picked suggestion position or "typed" | ~200 B each; 1 TB/day, 30 TB over the 30-day window | Log pipeline → data lake; kept 30 days |
| DailyQueryCounts | (day, locale, normalized query) | submitted count, per-day distinct submitters (each user once per query per day), selection count, HyperLogLog sketch of distinct hashed users | ~1 billion rows/day, mostly long tail | Daily batch job; kept for the window |
| SuggestionCorpus | (locale, query id) | text, decayed score, flags | ~100M queries; 2.5 GB of strings + 0.8 GB of score and flags | Index builder input, rebuilt daily |
| IndexSnapshot | version id (2026-10-11a) |
string table, node array, per-query metadata | ~20 GB, immutable | Builder writes it; serving nodes memory-map it |
| TrendingDelta | (locale, query) | query, trending score, flags | ≤ 100K rows, a few MB | Stream processor; replaced every minute |
| Blocklist | version id | exact strings, patterns, entity rules | Small | Policy service; pushed to all nodes within 5 min |
| PersonalHistory | user id | last 100 searches | ~2.5 KB/user; 500M users = 1.25 TB | Per-user KV store; read once per session |
Two decisions hide in that table. SearchLog records submitted searches and selections, never raw keystrokes (D8); otherwise partial words like chicago mar would become popular suggestions. And PersonalHistory, the only record keyed by a real user identity, stays out of the snapshot, which keeps the per-keystroke response identical for everyone and therefore cacheable (D5).
Sign in to continue reading
The rest of this lesson is available with a free account. Signing in with Google or Microsoft is free.
Sign in to read the full lesson